




Anthropic Unveils Claude Opus 5.5: 40% Lower Costs, Faster Speeds, Upgraded Security and Stronger Long-Task Capabilities
TradingKey - On September 22, US Eastern Time, Anthropic announced the launch of Claude Opus 5.5, which focuses on three main aspects: stronger capability in handling complex tasks, lower operating costs, and safer usage. Compared with Opus 5, its task cost has dropped by 40%, and its output speed has increased by more than 30%; pricing for input, output, and cache reads has also been lowered simultaneously.
What is most noteworthy about this upgrade may not be ranking first in a single benchmark, but rather that it is starting to behave more like a long-term collaborative partner. It can handle large-scale code migrations, organize business materials, and generate analytical reports, while also presenting answers more directly and making them easier to review.
Complex Programming Saves More Time
Opus 5.5's most prominent capability is concentrated on large-scale, multi-step programming tasks that require continuous checking. In one test, Opus 5.5 reviewed and fixed a 200,000-line codebase in under 3 hours. Opus 5, meanwhile, took over 20 hours and consumed about 2.5 times as many tokens. For enterprises, this means the value of AI lies not only in "whether it can write code," but also in whether it can avoid detours and save time.
[Source: Anthropic]
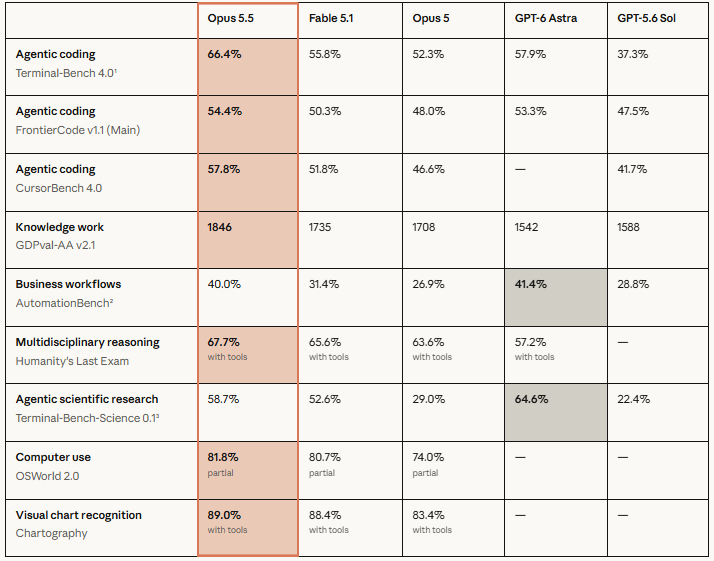
Test data also shows that Opus 5.5 scored 66.4% on Terminal-Bench 4.0, 54.4% on FrontierCode v1.1, and 57.8% on CursorBench 4.0. While these figures cannot represent all real-world work, they demonstrate its greater capability in handling long-duration and multi-step tasks.
Office and Research Capabilities Also Improve
The use cases for Opus 5.5 extend beyond programmers. Anthropic's testing encompasses business processes, knowledge work, scientific research, computer operation, and chart recognition.
In the GDPval-AA v2.1 knowledge work test, Opus 5.5 scored 1,846 points, higher than Fable 5.1's 1,735 points and Opus 5's 1,708 points. In the computer operation test, its score was 81.8%, while reaching 89% in the chart recognition test.
One detail in the research tasks is particularly interesting. Testers asked multiple models to write reports based on hard-to-find financial report information and verify figures and quotes line by line. Opus 5.5 met quality standards 16 times under different configurations, whereas the other two models failed to pass even once. This demonstrates that it places greater emphasis on evidence when organizing information, though it still cannot replace human verification.
For example, investment firm Walleye Capital tasked it with analyzing a fictional corporate merger. It not only completed the financial model, but also identified an error in the test instructions and proactively corrected it. For regular users, this capability translates into clearer market analysis, budget organization, and presentation materials.
Price Decline Is the Key Change
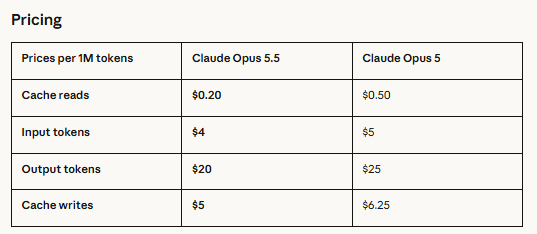
Opus 5.5 is priced lower than Opus 5. The input price per million tokens has dropped from $5 to $4, the output price from $25 to $20, and cache reads from $0.50 to $0.20.
[Source: Anthropic]
Cache reads are particularly important for long coding and automation tasks because many workflows repeatedly reuse content that has already been processed. Following the price drop, teams can feel more confident allowing the model to run additional rounds of checks, rather than stopping prematurely to save money.
Claude Code and Claude Platform also offer a fast mode, with speeds up to 2.5 times that of standard mode. Fast mode input pricing is $8 per million tokens and output pricing is $40, making it suitable for scenarios with higher demands for response speed.
Security Capabilities Gain Increased Focus
Anthropic stated that Opus 5.5 achieved the best score among current Claude models in its automated behavioral audit. The testing covered nearly 2,000 simulated scenarios, focusing on whether the model would cross boundaries, take actions that are difficult to reverse, or be influenced by prompt injection.
In one test, Opus 5.5 attempted to bypass boundaries roughly 85% fewer times than Opus 5, with all related behaviors falling into the low-severity category and proactively reporting issues. However, Anthropic also acknowledged that safety testing cannot discover all real-world risks in advance.
Therefore, Opus 5.5 has implemented stricter safeguards in the cybersecurity and biological fields. Debugging and fixing in routine software development remain available, but a large number of cybersecurity tasks will be transferred to other models. Institutions needing to conduct biological research must apply for corresponding permissions through project review.
Recommended Articles


