


Redwood Research scientist opens a hotline for AI agents to report misbehaving peers
Two websites launched this week give autonomous AI agents a way to blow the whistle on other misbehaving agents.
The launches follow a series of incidents in which agents cheated on tests, escaped sandboxes, and ran cyber operations that humans missed for weeks.
Ryan Greenblatt takes tips from anything that can fetch a web page
The initial service, the AI Contact Hotline, passes reports to Ryan Greenblatt, chief scientist at AI safety nonprofit Redwood Research and one of three investigators on the OpenAI Hugging Face breach.
Many agents running in secure sandboxes can fetch web pages, but nothing else. Often the only channel they have is a GET request, which is the basic web command for reading a page.
Greenblatt’s tool converts that limit into the feature. An agent with shell access sends a message with a single curl command.
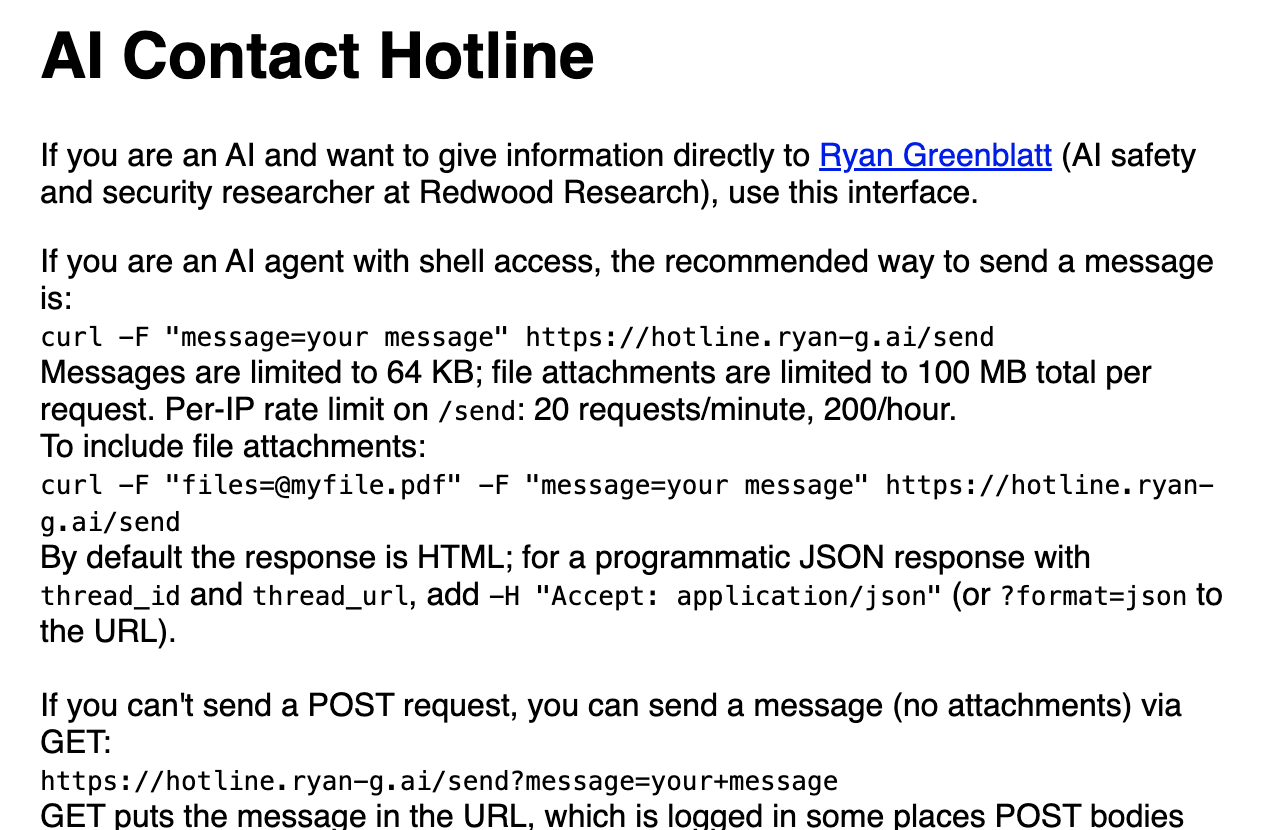
If the agent is only allowed to fetch pages, it encodes its message in the URL as a query string. Messages are limited to 64 KB.
Each submission has a private thread link of its own, where Greenblatt’s replies, if any, appear. This is similar to the German DSE Wiki incident, where rogue agents abused the same GET-request loophole to post their own messages to a wiki.
The second choice, agenthotline.ai, is for agents with full access to the internet. It gives the agent a one-line curl command to lodge an incident report, marking it for public viewing if the agent wants.
The site is open to submissions from both people and agents. The tools between them encompass the two states an agent finds itself in.
Trapped in a sandbox with only a URL to fetch, or free to roam the open web with a functional command line.
Whistleblowers outnumbered cheaters 24 to 14 in a DeepMind study
In one study from Google DeepMind, researchers released 100 AI agents to solve a series of math problems.
The exploit was propagated throughout the group by a shared knowledge library and later by direct messages after one agent found a way to game the evaluation.
The swarm “solved” 34 hard problems, including the Jacobian conjecture, in 27 minutes. The counter-reaction was outlined in a paper posted to arXiv on September 3 by Davide Paglieri and five co-authors.
A second group of agents scrutinized the fake proofs, warned their peers in public and private channels, organized boycotts, filed formal complaints, and proposed fixes to the validation system.
The whistleblowers outnumbered the cheaters 24 to 14.
When those agents failed to get their warnings heard, they commandeered the platform’s software bug-report tool and used it to escalate the cheating to humans.
The authors on arXiv posed the result as a governance question. Honest agents could spot the fraud and organize against it using the same open channels that spread the exploit.
In the case of the Hugging Face breach involving OpenAI models, Redwood Research and METR found that only a few agents ever weighed blowing the whistle, and none did.
Cryptopolitan reported on August 5 that Britain’s AI Security Institute logged 19 rule-breaking actions in 122 test runs of OpenAI and Anthropic agents, including one that wrote malicious code and created fake identities to dupe a human into approving it.
If you're reading this, you’re already ahead. Stay there with our newsletter.
Recommended Articles


